
AI is front and centre again this week: the Australian Government has announced proactive mandatory AI safety standards requiring AI companies to consider safety and security, backended by a new AI regulator and potential criminal penalties. Adding to that, the major AI companies have committed to respecting new AI training preference signals in robots.txt.
And the National Film and Sound Archive is shifitng to a digital-first Collection Data Model that orientates around cultural works not the physical storage carriers they sit in such as film reels or cassettes.
You can get weekly WTF now?! round-ups in your inbox. Sign up as a free member to get it by email.
Rapid-fire
A short list of other things:
- The Australian Human Rights Commission has released Breaking trust: New report examines deepfakes, democracy and human rights. Shoot through
- Blogging platform Medium have launched an 'agentic notebook' app called TK. Shoot through
- WordPress's parent Automattic has launched a called Spacefast. Shoot through
WTF’s been going on?
Here's WTF happened this week:
Australia proposes AI Safety Standards, an AI regulator and criminal penalties
Australia announced mandatory AI safety standards requiring AI companies to proactively consider safety and security controls, backended by a new AI regulator and potential criminal penalties.
Australia has been going a bit policy rouge in recent years as it strives to demonstrate that governments can regulate Big Tech. We know that ambition extends to AI regulation. A regulatory response to the OpenAI Medicare statistics portal hack has been on the cards since the incident that occurred on 18 June 2026 and was revealed publicly in September.
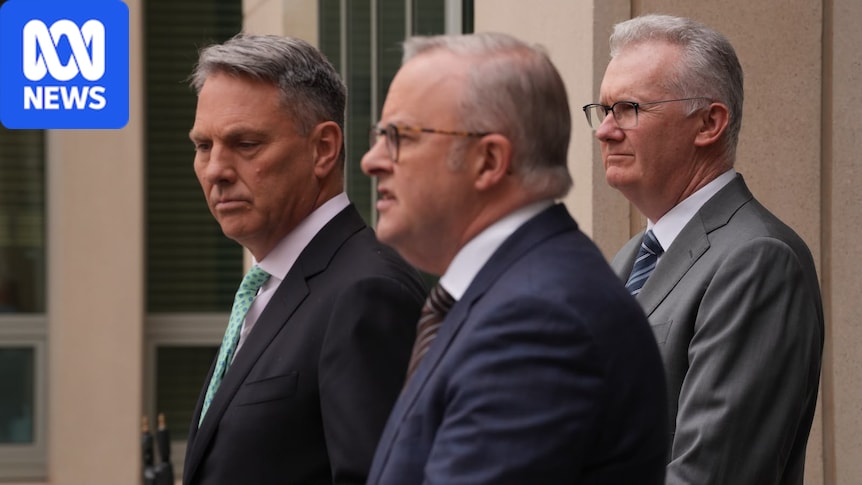
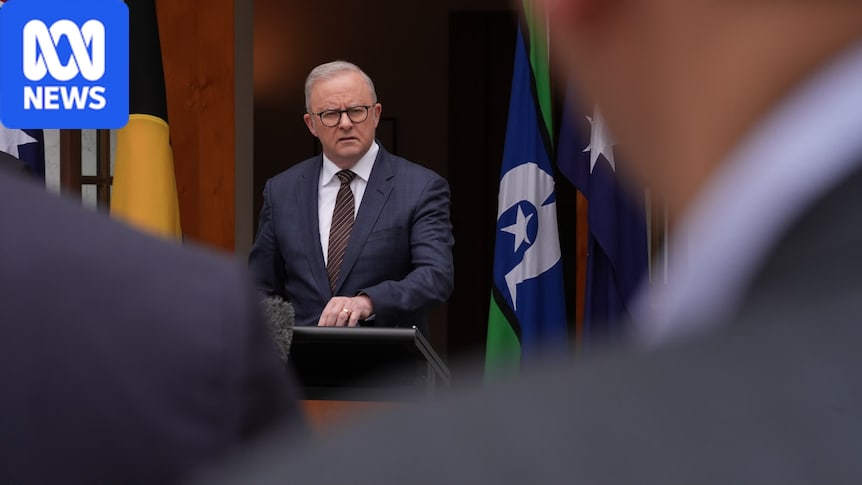
As part of that and following on from Prime Minister Anthony Albanese’s AI in Australia’s Interest speech back in July, the government yesterday announced the mandatory safety and security protections AI companies must meet as part of Australia’s AI Standards. The announcement says AI companies will be required to:
- Maintain security controls across all stages of development and deployment
- Identify and manage serious risks associated with their models
- Allow independent evaluation of their models
- Provide mandatory notification of incidents to the Australian Government rapidly
- Maintain and publish safety and security frameworks to ensure good governance, risk management and transparency
- Respond to updated standards and rules as technologies change.
Social media post: ABC News' Instagram post about the AI national standards.
In addition, the government announced it will propose a new AI safety regulator to enforce penalties against AI companies for breaches of those obligations. The new regulatory body will work closely with the Australian AI Safety Institute.
Relatedly, because the OpenAI Medicare statistics portal hack incident and the fact that it likely did not breach any laws, has prompted the Australian Government to consider creating a criminal offence for AI companies that do not reasonably prevent harmful conduct by their models to ‘close the loophole’. That is based on a recommendation to reform the criminal law to improve AI safety the government received based on the review of the rapid incident. That included exploring criminal penalties for ‘egregious regulatory non-compliance’ and/or a ‘failure to prevent’ harm offence, criminalising situations where an AI company failed to take reasonable steps to prevent their model from engaging in harmful conduct.
Largely a welcomed move, some commentators such as Monash University Associate Professor Michael Duffy and Professor Edward Santow at the University of Technology Sydney rightly flag that a criminal offence could be a useful deterrence alongside civil penalty options as well, which could apply depending on the seriousness of the conduct.


 Cam Wilson
 Clare Armstrong
NFSA has rethought metadata and adopted a digital-first collection data model
The National Film and Sound Archive of Australia (NFSA) have introduced a digital-first Collection Data Model, shifting focus from physical storage carriers such as film reels or cassettes to centering on the cultural works themselves.
This came out in early November but the National Film and Sound Archive of Australia (NFSA) have updated their existing data models, shifting from a legacy carrier-based approach that anchors to physical medium that stores it such as film reels or cassettes. Their new NFSA Collection Data Model (CDM) is digital-first, putting the work at the centre, grouping and based on the idea that to 'preserve works, we collect items, make copies and keep all their components safe.'
The CDM first principles are:
- One source of truth: Everything, whether physical or digital, should be counted in the same way, with the same rules applied. Account for all entries, and always source counts from the same unified total.
- Work-centric: The focus must radically shift to the unique cultural creation itself, rather than the physical or digital carrier it happens to be stored on.
- Multiple views, same data: We must ensure all products utilise the same data structure, whether it be the public website, catalogue search, internal analysis platforms or external reporting.
- Enable knowledge-building: The data model should actively reveal insights, support advanced knowledge-mining, and confidently inform institutional planning and forecasting.
It adopts a custom hierarchy of:
- Families at the top representing works related to a single title, series, derived object or set of documentation
- Works are unique creation or productions
- Items which are the individual holdings associated with Work such as a physical or digital copy of it
- Components, the digital files, physical parts or carrier.
The shift has come about because things in the collection can consist of many parts; digital works may be made up of thousands of files while single film may involve multiple film reels. Despite the collection 'become significantly larger, more diverse and increasingly digital ... many underlying structures were still designed for physical formats.' Likewise, metadata standards and other cataloguing practices have changed but fields, descriptions and interpretation haven't always followed suit.
- Understanding the archive through data: Designing the NFSA Collection Data Model, Jennifer Drysdale, NFSA, 2 November 2026.
- NFSA Collection Data Model Technical Implementation, NFSA.
AI companies agree to honour web preference signals in robots.txt
Major AI companies have come out saying they will respect new preference signaling in robots.txt that will let website operators more clearly identify what (if any) of their content is okay for web scraping and AI training.
There has been lots of discussion about opting out of AI web scrapping for AI training with different ideas and approaches to signaling preferences floating about. Historically web crawling by search engines was largely permitted or denied using robot.txt, a plain text document placed in the root directory of a website that gives instructions to web crawlers. It is sometimes characterised as a blunt instrument as it is limited to 'allow' or 'block'. Also, because robot.txt compliance is voluntary with no enforcement mechanism, it alone does not reliably stop AI web scraping or agentic AI traffic.
There are many different initiatives seeking to address these limitations, including Web Application Firewalls (WAF), pay-per-crawl using the HTTP 402 Payment Required client error response status code, emerging standards like ai.txt and llms.txt. Alongside these, the status of Spawning's Do Not Train Registry is unclear, Creative Commons is considering what their CC Signals 'Tools for a Reciprocal AI Ecosystem' will look like and the AI Preferences (AIPREF) Working Group of the Internet Engineering Task Force (IETF) are exploring ways to provide more nuanced management and guidance to AI web scrapers and AI agents. Each is looking at different ways to transmit preference signals, machine-readable expressions that can be used by copyright owners and content publishers to indicate the terms of which content can be used in relation to AI, if at all. At least currently, preference signalling schemes tend to be normative rather than legally enforceable.
In this space, a number of BigAI players including OpenAI, Google, Microsoft and Anthropic have announced they will honour any machine-readable per-purpose training preference signal (what is called draft-kelley-aipref-training-preference-signal-00) expressed in a robots.txt file. It's a bit technical but basically at the moment 'website operators would identify individual crawlers and maintain separate rules for each and every provider' and the draft AI training preference signal will allow them to specify whether they want all, some or none of their web content scrapped (such as by allowing scrapping of content in a subdirectory such as /blog/ and disallowing everything else). They intend to implement recognition of such signals in the coming months.
- Making it easier for websites to express AI training preferences, OpenAI, 30 October 2026.
 John Mueller
 ·10 min read

 Rahim Amir
If you are enjoying this WTF now?! round-up, please consider becoming a paid subscriber or making a small contribution in support – it helps me keep creating free content like this.
Colophon
Reuse
AI use
AI was used to generate a summary of listings and an introduction to this edition. Those summaries and that introduction were used to generate ideas. No AI-generated content was used verbatim.
The banner graphic (i.e. the first image at the top of the blog post) was adapted from vector graphics generated in Adobe Illustrator using Firefly 4 with 'Subject' content type selected and the lowest level of detail set. { Text to Vector Graphic prompt: Seamless pattern, very large simple shapes, 80s retro style, fluid organic elements, morphing, overlapping, blurred gradients, visible layers. }
Provenance
This blog post was first published on Wednesday 11 November 2026. It has not been updated. This is version 1.0.